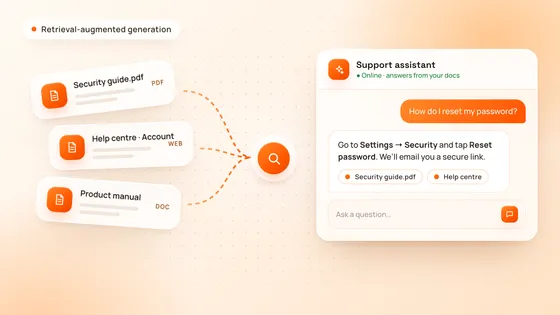
What Is RAG (Retrieval-Augmented Generation)? A Plain-English Guide
RAG lets an AI assistant answer from your own documents instead of guessing. How retrieval-augmented generation works, when you need it, and RAG vs fine-tuning.
RAG Development
We build retrieval-augmented generation (RAG) systems that connect AI to your documents, help centre and databases, so every answer is grounded in your information, links to its sources and respects who is allowed to see what.
Our core stack
What We Build
General AI models know a lot about the world and nothing about your business. RAG finds the right passages in your own content for each question and gives them to the model, so it answers with your facts instead of guessing.
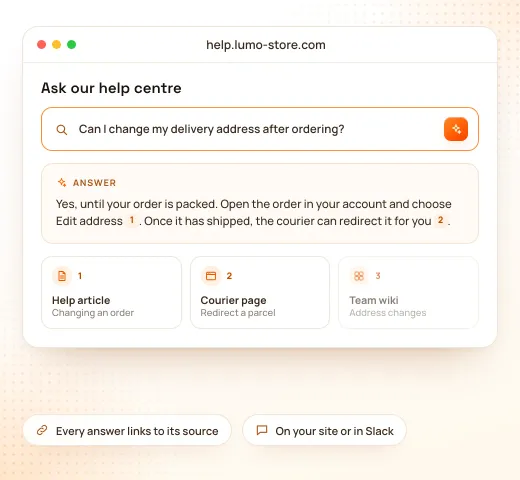
An assistant that answers questions from your documents, wiki, help centre and policies, with a link to each source, for customers on your website or for your own team in Slack or your intranet.
What we do:
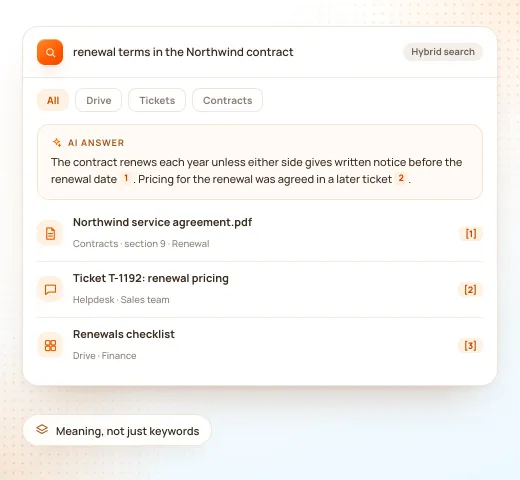
Search that understands meaning, not just keywords, across your drives, tickets, contracts and records, with short AI answers on top and the matching documents underneath.
What we do:
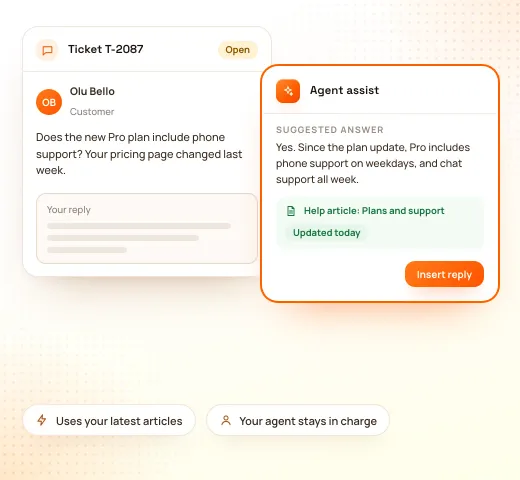
Customer support chatbots and agent assistants that answer from your latest help articles and product documents, so answers stay accurate when your products and policies change.
What we do:
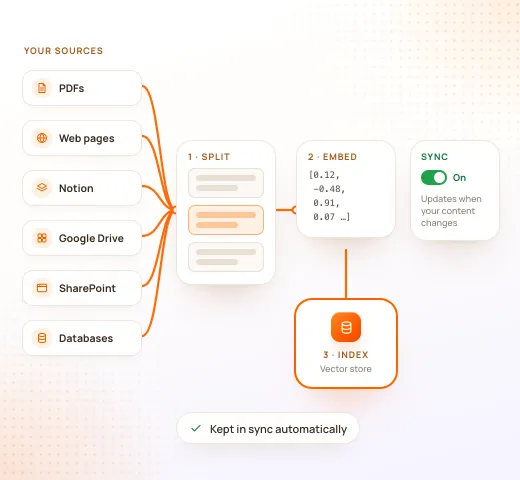
We bring in PDFs, web pages, Notion, Google Drive, SharePoint and databases, split them into useful passages, create embeddings and keep the index in sync as your content changes.
What we do:
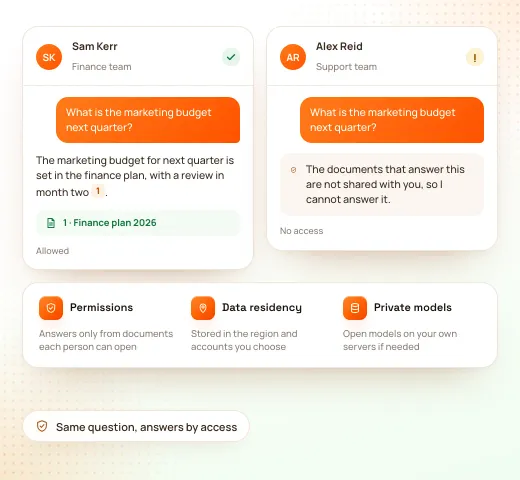
Each user only gets answers from documents they are allowed to see, data stays in the region and accounts you choose, and sensitive content can stay on your own servers with open models.
What we do:
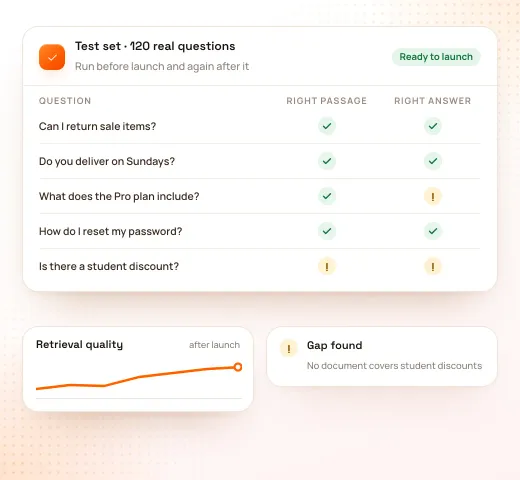
Before launch we build a test set of real questions and measure how often the system finds the right passage and answers correctly, then keep measuring after launch to catch problems early.
What we do:
How We Work
You see the system answer from your own content before we build the rest.
A free 30-minute call on your content, your users and the questions they ask.
Your sources checked for quality, structure, access rules and freshness.
A first prototype answering from your own content in 72 hours.
Pipelines, search and interface built, then measured on real questions.
Live, kept in sync with your content and monitored for accuracy.
Why Choose Us
A RAG system is only useful if people can trust its answers.
Most wrong answers start with the wrong passage, so we tune search before prompts.
We test on your real questions before launch and keep measuring after it.
Every system handles 10× the current load, and more documents than you have today.
LangChain or LlamaIndex, pgvector, Pinecone or Weaviate, chosen for your data and budget.
Code, pipelines and documentation are yours once the project is paid in full.
A RAG assistant starts at $999, with one assistant that answers from your documents, a website widget and source links. More data sources, access control and integrations with your systems are quoted after the strategy call.
| Project | Starting price | Includes | Typical timeline |
|---|---|---|---|
| AI chatbot / RAG assistant | $999 | One assistant that answers from your documents, a website widget and source links | Agreed on the call |
A fully custom UI/UX design adds 25% and faster delivery adds 25%.
Build my estimateFrom our blog
RAG lets an AI assistant answer from your own documents instead of guessing. How retrieval-augmented generation works, when you need it, and RAG vs fine-tuning.
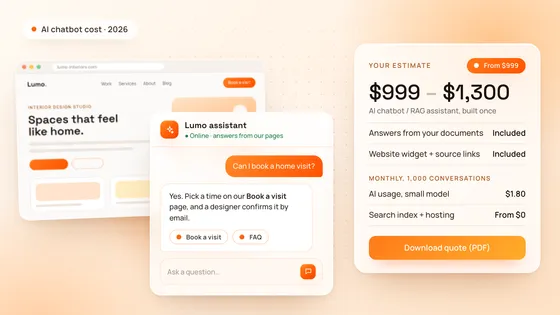
What an AI chatbot costs in 2026: from $999 for a custom assistant that answers from your documents, plus monthly AI usage, tool prices and real examples.
Got Questions
Retrieval-augmented generation (RAG) is a way of making an AI model answer from your own information. For each question the system searches your documents for the most relevant passages and gives them to the model, which writes the answer from them and can link to its sources.
When answers must come from your own content, such as product details, policies, contracts or internal processes, and that content changes over time. A model on its own does not know your business and may guess; RAG gives it the right facts for each question.
For answering from your knowledge, usually yes. RAG uses your latest content without retraining, shows its sources and respects access rules. Fine-tuning is better for teaching a model a style or format, and the two can be combined.
Each user only gets answers from documents they are allowed to see, data stays in the accounts and region you choose, and we use AI providers’ paid APIs that do not train on your data by default. For the most sensitive content, open models can run on your own servers.
At TechNamah a RAG assistant starts at $999, with one assistant that answers from your documents, a website widget and source links. Extra data sources, access control and integrations are quoted after a free 30-minute strategy call.
Yes. Once the project is paid in full, the code, pipelines and documentation made for you are yours, as our Terms of Service set out, and your data stays in your own accounts.
Ready to Start?
Book a free 30-minute strategy call and tell us what your AI should know. We reply to every request within 24 hours.